Balyasny Asset Management, a roughly $38 billion AUM hedge fund with about 2,000 staff, doesn't take a model vendor's benchmark scores at face value. On 18 September 2026, Claude published an interview with Charlie Flanagan, BAM's Chief AI Officer, walking through the evaluation methodology the fund uses before trusting a new model with real trading and investment work, and why Claude Fable 5 passed it.
Why BAM Built Its Own Evaluation Harness
Flanagan's framing is that 2026 is the year AI shifted from systems that search for information to systems that actually do work, and that shift has been driven as much by the harness around a model, such as Claude Code, as by the model itself. BAM invested years ago in evaluation infrastructure built from thousands of real financial tasks with verifiable outcomes across equities, macro and commodities, and it tests two different things: the raw model's capability, and how that model performs inside BAM's own agentic harness, using the exact same tools, files and requirements its analysts use day to day.
What Does BAM's Model Evaluation Actually Test For?
BAM's evaluation doesn't stop at whether a model gets the right final number. It scores planning quality, tool use, evidence analysis, error recovery and self-checking, and it specifically hunts for the failure modes that matter most in financial work: numerical errors, missed coverage of relevant material, conclusions the underlying evidence doesn't support, and retrieval problems where the model cites something that isn't actually there. That's a materially higher bar than a general capability benchmark, because a model can write fluent, confident-sounding analysis while still failing every one of those checks.
The Result: 89.4% vs 86.1%, and a Genuinely Unsolved Problem
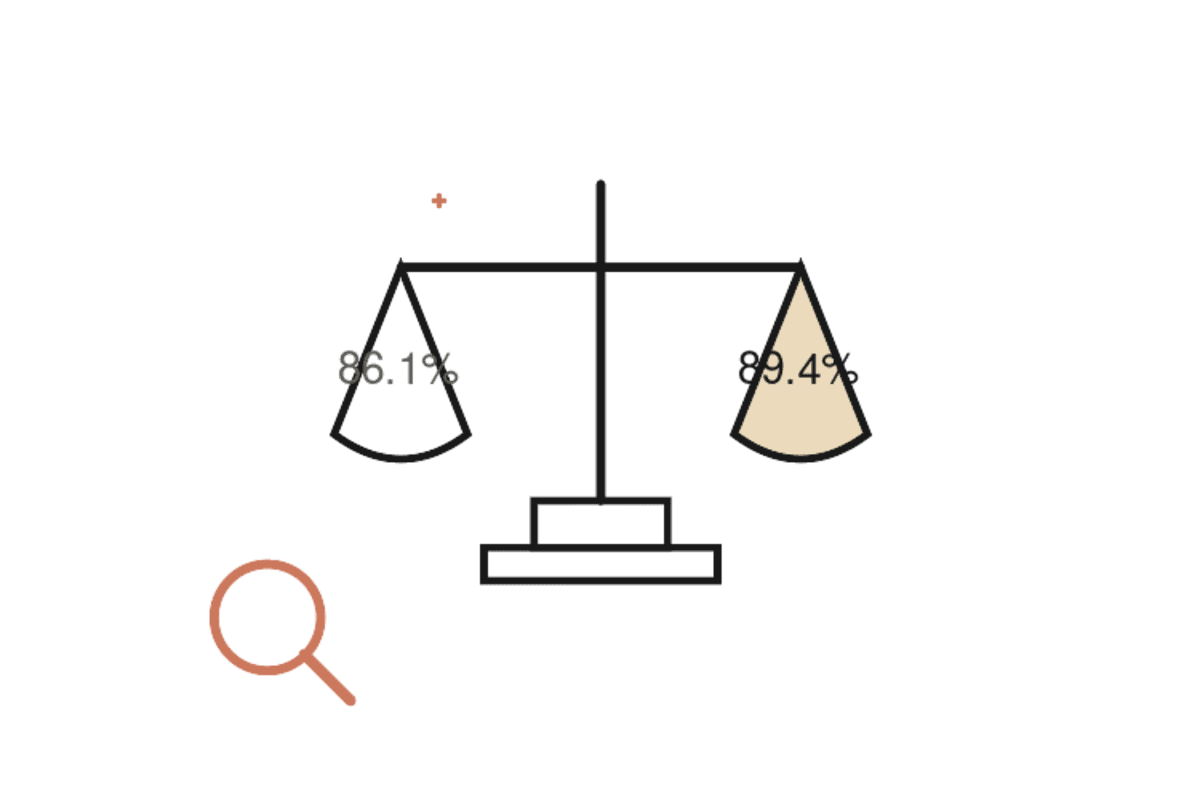
Claude Fable 5 scored 89.4% on BAM's relevant task subset, against 86.1% for the prior production model, with the largest gains showing up in complex planning, analysis and agentic execution.
A merger-arbitrage deal-analysis package, estimating close probability and timeline, extracting terms, and flagging items that need investor judgment, dropped from 3 to 5 days down to under a day, with the agent itself running for roughly 30 minutes.
Every material output still goes through mandatory human review before anyone relies on it. The speed gain sits in front of that review, not instead of it.
Fable 5 was the first model to solve a set of previously unsolved economics problems in BAM's own test set. BAM didn't just accept that result: it re-ran the evaluation, independently checked the scoring, and reviewed the outcome with Anthropic before treating it as real.
BAM's evaluation approach versus taking vendor benchmarks at face value
| Question | Vendor benchmark alone | BAM's own evaluation |
|---|---|---|
| What's tested | General capability tasks | Thousands of real financial tasks with verifiable answers |
| Where it's tested | Model in isolation | Model inside BAM's own agentic harness and tools |
| What's scored | Final answer accuracy | Planning, tool use, error recovery, self-checking |
| What happens to a surprising result | Reported as-is | Re-run, independently checked, reviewed with the vendor |
What This Means for AU Financial Services
An Australian fund manager, insurer or advice practice doesn't need BAM's scale to borrow BAM's discipline. The lesson isn't "adopt Claude Fable 5", it's "build a small, honest evaluation set from your own real tasks before you trust any model with anything that touches client money", and then keep mandatory human review sitting in front of anything material, exactly as BAM does. For a mid-sized AU advice or funds business, that might mean 30 to 50 representative tasks with known-correct answers, run against the model inside the actual tool it will operate in, not a generic chat window, before a single production workflow changes.
The other detail worth sitting with is BAM's response to Fable 5 solving problems that had been unsolved in its own test set. The instinct to treat a surprisingly good result as a red flag rather than a win, and to re-verify it independently before accepting it, is exactly the muscle a lot of businesses skip when a new AI capability looks impressive on first use. That discipline is cheap to build early and expensive to build after something has already gone into production on an unverified result.
Flanagan's point about harnesses mattering as much as models is worth dwelling on too. BAM didn't just swap one model for another inside an unchanged workflow, it tested Claude Fable 5 inside the same agentic harness, tools and files its analysts actually use, which is closer to how Claude Code gets deployed in a real business than a side-by-side chat comparison ever is. An AU business piloting Claude Code should expect the harness, not just the model, to account for a meaningful share of whatever productivity gain shows up.
If you're weighing how to evaluate Claude Fable 5, Claude Code, or an agentic workflow for your own financial services or professional practice, that scoping and evaluation design is exactly the kind of work we do. Have a look at our services, read more on our blog, or get in touch to talk through what an evaluation set for your business would actually look like.